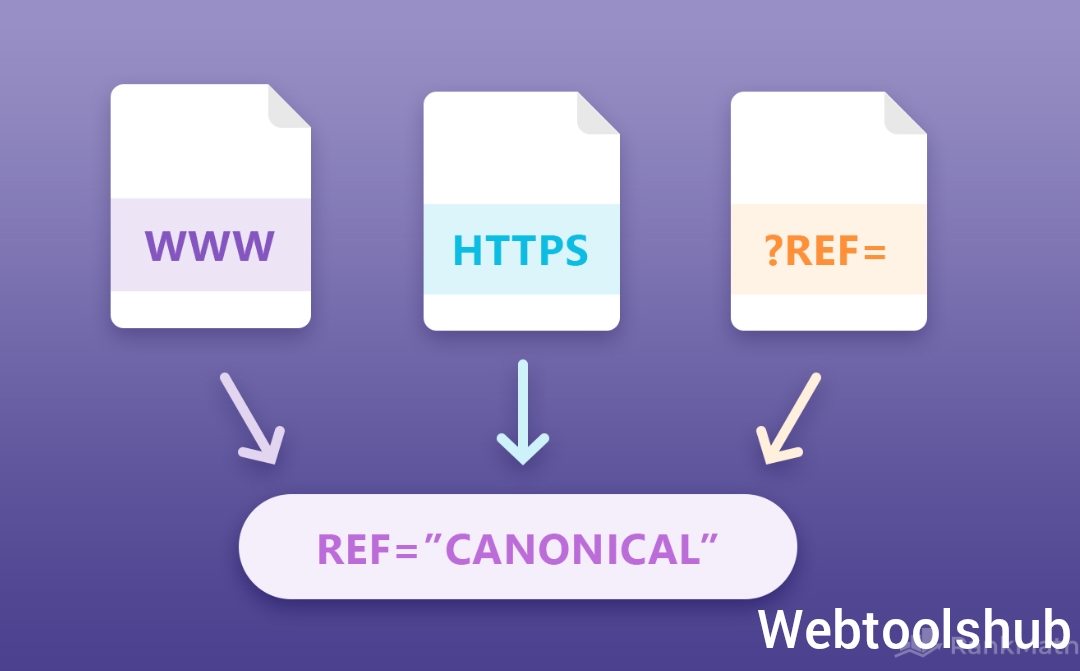
Understand canonical tags, clean URLs, duplicate paths and redirect behavior so search engines can identify the preferred version of a page. This guide is written for people who want to complete the task correctly, understand the trade-offs, and know what to check before relying on the result.
What this task actually involves
Canonical URLs Explained for Static Websites is easier when the goal is defined before the tool or setting is chosen. The important variables are not just speed or output size; they include accuracy, compatibility, privacy, readability, repeatability and what the final file or result will be used for.
For a small website such as WebTools HUB, the useful standard is practical: a visitor should be able to understand the feature, complete the task, recover from common errors and verify the output without needing specialist knowledge.
When this workflow is useful
This approach is especially useful when you need a repeatable result rather than a one-off experiment. It also helps when several people share the same process, because a checklist reduces avoidable differences between outputs.
- one preferred URL per article
- HTTPS and hostname consistency
- query parameters
- redirects versus canonical hints
A practical step-by-step workflow
- Choose the public URL format.
- Use HTTPS consistently.
- Set one self-referencing canonical on each important page when appropriate.
- Redirect obsolete duplicate paths.
- Make internal links use the preferred URL form.
What to check before you start
The first useful check is whether the input and the intended output actually match. For this topic, that means paying attention to one preferred URL per article, HTTPS and hostname consistency, query parameters, and redirects versus canonical hints. These are not separate SEO phrases; they are practical variables that can change the result.
It is also worth deciding what “good enough” means before processing anything. A private draft, a public-facing asset and an official document can have very different requirements for quality, privacy, compatibility and repeatability.
How the right choice changes by use case
For a personal task, convenience may be the main priority. For a business workflow, consistency, file naming and repeatability become more important. For a public website, accessibility, performance and predictable behavior matter as well. The same setting can therefore be appropriate in one situation and excessive in another.
When the output will be shared with other people, add one more verification step: open it outside the environment in which it was created. This catches problems such as missing fonts, unexpected page dimensions, broken links, weak contrast or device-specific layout issues.
How to troubleshoot a disappointing first result
If the first result is not useful, change one variable at a time rather than rebuilding the entire workflow. Common causes include canonicalizing unrelated pages, pointing every page to the home page, mixing www and non-www URLs without a strategy, and leaving old .html and clean URLs indexed without redirects. Each problem should lead to a specific correction, followed by another check of the final output.
Keep the original input whenever possible. That gives you a reliable comparison point and prevents a low-quality intermediate result from becoming the only available copy.
Quality control that is easy to repeat
A useful quality-control routine can be short: confirm the input, perform the task, inspect the output, test the most important edge case, and record any setting that affects future results. This is especially valuable for websites and tool workflows because small changes can otherwise create silent regressions.
For WebTools HUB readers, the same principle applies to the site itself. A guide should explain the decision, the tool should perform the task, and the final result should be easy for a visitor to verify. Keeping those three layers consistent creates a better experience than adding more keywords or decorative sections.
How to judge the result
Do not evaluate the output only from the final download message. Open or use the result in the context where it matters. A document should remain readable, a QR code should scan from its intended distance, a web page should remain usable on a phone, and a technical SEO change should produce consistent URLs and crawlable pages.
Decision guide
| Area | What to check |
|---|---|
| Primary goal | Complete the task reliably |
| Quality check | Inspect the actual output |
| Performance check | Measure bytes, time or responsiveness where relevant |
| Safety check | Confirm privacy, permissions and input limits |
| Maintenance | Keep the workflow documented and repeatable |
Common mistakes and how to avoid them
- canonicalizing unrelated pages
- pointing every page to the home page
- mixing www and non-www URLs without a strategy
- leaving old .html and clean URLs indexed without redirects
Privacy, accessibility and performance considerations
Good utility pages explain what happens to user input, especially when files, URLs or account-related data are involved. If processing happens in the browser, the implementation should actually match that claim. If a file is uploaded to a server, the page should explain the relevant processing and retention behavior.
Accessibility and performance are also part of the feature. Use readable text, keyboard-friendly controls, meaningful labels, stable layouts and appropriately sized assets. A technically correct tool is still frustrating if the interface is slow, confusing or difficult to operate on a phone.
How to apply this guide on a real project
Start with one representative example instead of changing an entire library or site at once. Keep the original input, document the result, and compare the before-and-after state. This makes it easier to reverse a poor change and gives you a repeatable reference for future work.
Final verification checklist
- Confirm the output matches the intended task and format.
- Check the result on the device or workflow where it will actually be used.
- Look for missing content, broken links, layout problems or unexpected quality loss.
- Confirm that privacy and permissions match the way the feature is being used.
- Keep the original source when the task is destructive or difficult to reverse.
- Record any important settings so the process can be repeated consistently.
Frequently asked questions
What is a canonical URL?
It is the URL you identify as the preferred version of a page when duplicate or near-duplicate URLs exist.
Is canonical a redirect?
No. A canonical tag is a hint in the page markup. A redirect actually sends the user and crawler to another URL.
Should every page canonicalize to itself?
For many standalone pages, a self-referencing canonical can make the preferred URL explicit, but it should match the actual canonical page.
What about query parameters?
If parameters create tracking or sorting variants, the canonical strategy should point to the clean content URL when appropriate.
Can two different articles share a canonical?
Only when they are genuinely duplicates or one is the preferred version. Otherwise, each article should have its own canonical.
Should canonical URLs use HTTPS?
Yes, when HTTPS is the public canonical protocol.
Why are canonical mistakes serious?
They can send conflicting signals about which page should be indexed.
How do I audit canonicals?
Compare the canonical tag, final URL after redirects, sitemap URL and internal links.